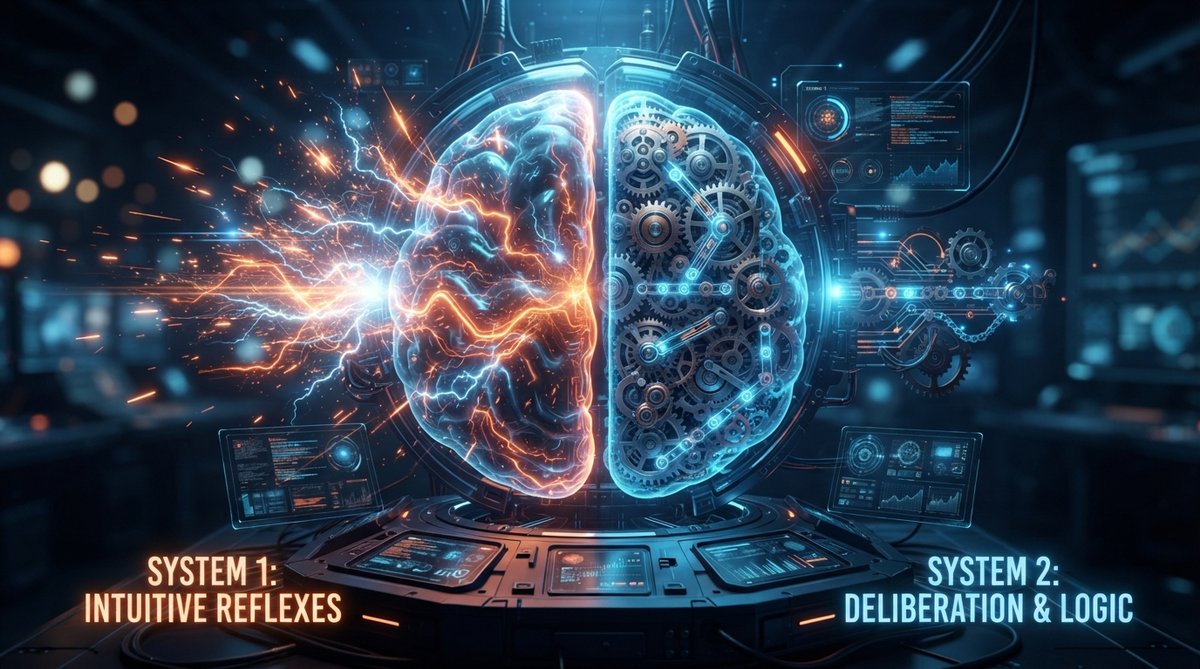
In his seminal 2011 book Thinking, Fast and Slow, Nobel laureate Daniel Kahneman introduced a framework that has since become the gold standard for understanding cognition. He categorized human thought into two systems: System 1, the fast, automatic, and intuitive reflex, and System 2, the slow, deliberative, and logical processor [1].
For the past few years, the AI industry has operated almost exclusively in "System 2" mode. We have been training increasingly massive, autoregressive models to perform every task—from writing creative essays to selecting a database tool—via a slow, token-by-token generation process. But as we transition toward autonomous agents, this "one-size-fits-all" approach is hitting a wall. We are now seeing the emergence of a new breed of low-latency, non-autoregressive models, such as the JEV architecture, that are finally bringing "System 1" reflexes to the AI stack [2].
The Architecture of Intuition
The inherent latency of traditional LLMs stems from their autoregressive nature: they generate text one token at a time, where each new token depends on the previous ones. This creates a computational bottleneck that makes them ill-suited for high-frequency tasks.
The new wave of System 1 models—exemplified by JEV—abandons this sequential generation [2]. Instead, these models operate via non-autoregressive parallel sampling. By ingesting a state and evaluating pre-declared schema questions in a single forward pass, they bypass the need for multi-second decoding loops. Because the output space is strictly bounded by schema primitives, these models can eliminate common "hallucinations"—they simply cannot generate off-schema text or invalid tool names. The result is a sub-500ms response time that transforms AI from a slow consultant into a reactive, high-speed participant in software workflows [2].

Enhancing Agentic Performance
In autonomous agents, speed is not just a convenience; it is a fundamental requirement for usability. When an agent is forced to perform a chain of ten tool-use decisions, each waiting on a 200ms+ network round-trip to a heavy chat completion endpoint, the total latency can easily exceed three seconds [3].
Moreover, as noted in recent research like the "Agentic Fast-Slow Planning" (AFSP) framework, the real breakthrough lies in hierarchical decoupling [4]. By keeping perception and reflexive planning on the edge—and reserving cloud-based, heavy "System 2" reasoning for truly ambiguous cases—we can build systems that remain responsive under pressure [4]. Some developers are even advocating for "blittable" in-process execution, moving these models out of HTTP-call-gated architectures and directly into the runtime to achieve microsecond-level reflexes [3].
The Trade-offs: Trust and Calibration
Applying Kahneman’s framework to AI forces a difficult question: When should we trust our reflexes?
In humans, System 1 is prone to cognitive biases; in AI, it is prone to overconfidence. Traditional models fine-tuned with Reinforcement Learning from Human Feedback (RLHF) are often rewarded for being persuasive, which can mask errors.
To mitigate this, the industry is shifting toward Reinforcement Learning for Calibrated Decisions (RLCD) [2]. Unlike standard RLHF, RLCD trains models to output statistically accurate confidence scores. This allows for "confidence-gated routing":
- High Confidence (e.g., > 0.85): The system relies on the System 1 reflex, executing the decision immediately [2].
- Low/Ambiguous Confidence (e.g., < 0.85): The system triggers a "System 2" intervention, routing the task to a larger reasoning model or a human reviewer [2, 5].
By treating the "System 1" model as a gatekeeper rather than a universal solver, we can maintain the safety guardrails that business-critical applications require [2].
Future Outlook
The future of AI infrastructure isn't about choosing between speed and accuracy; it is about building a hybrid stack. We are moving toward an orchestrated architecture where fast decision nodes filter traffic, sanitize inputs, and execute routine tool-calls at the network edge, while massive reasoning engines sit in the background, invoked only when the complexity of the task demands deep, deliberate synthesis [5].
As we continue to optimize the "reflexes" of our AI systems, we will find that the most powerful agents are those that know exactly when to stop thinking—and start acting.
Sources
[1] Title: Thinking, Fast and Slow - https://en.wikipedia.org/wiki/Thinking,_Fast_and_Slow [2] Title: How TypeSafe Jev Delivers Zero Hallucination AI - https://www.atlascloud.ai/blog/tips/typesafe-jev-zero-hallucination-latency [3] Title: Why Is Your “Fast” System 1 AI Still Sitting Behind an HTTP Call? - https://dev.to/iancowley/why-is-your-fast-system-1-ai-still-sitting-behind-an-http-call-jev-2g4e [4] Title: Bridging Large-Model Reasoning and Real-Time Control - https://arxiv.org/html/2604.01681v1 [5] Title: Thinking Fast and Slow in AI Agents - https://medium.com/syncedreview/thinking-fast-and-slow-google-deepminds-dual-agent-architecture-for-smarter-ai-d49a0285473f